01Bounding boxes
2D Bounding Box Annotation
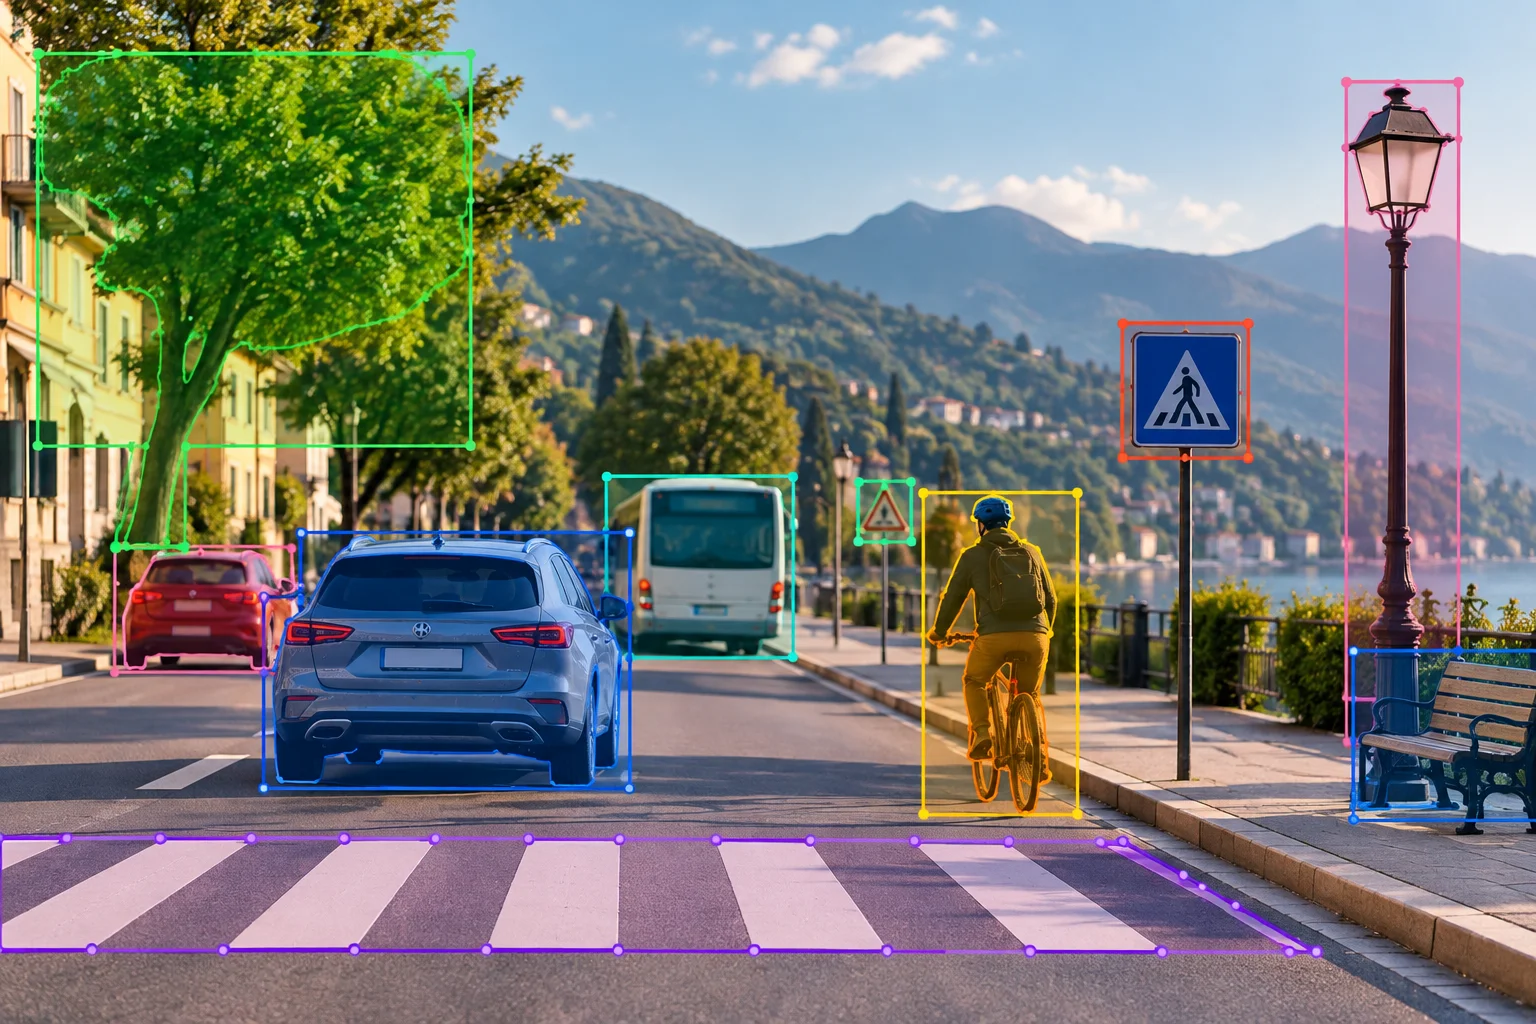
A rectangular box is drawn around each object of interest in an image, marking its position and boundaries for object detection models.
AI Data Operations
From 2D bounding boxes to full scene segmentation, our in-house domain expert annotation teams label your image data with the accuracy and consistency your models need to perform.
Capabilities
All annotation types and techniques, one annotation partner.
CAPABILITY / 01
A rectangular box is drawn around each object of interest in an image, marking its position and boundaries for object detection models.
A 3D bounding box is drawn around an object, giving depth information that a flat 2D box cannot.
A multi-point outline drawn around the exact, irregular edges of an object, used when a rectangular box would include too much background or miss the object's true shape.
Individual points marked on specific, identifiable parts of an object, such as joints on a body or corners on a face, are used to track structure and movement.
A connected line drawn along a linear feature in an image, following its path rather than its area.
Every pixel in an image is assigned to a category, so the model understands not just where an object is, but the full extent of every surface and region in the frame. FSL (Few-Shot Learning) segmentation extends this to scenarios with limited labelled examples.
A combined approach that segments every pixel in an image while also distinguishing between individual instances of the same object class, merging the completeness of semantic segmentation with the object-level precision of instance segmentation.
The mapping of a subject's skeletal structure and joint positions across a sequence of images or video frames is used to understand posture, movement, and motion over time.
Assigning one or more category labels to an entire image, without marking the specific location of objects within it.
Every individual object in an image is outlined at the pixel level and treated as a distinct instance, even when multiple objects of the same category overlap or sit close together.
A descriptive, natural-language caption is written for an image, objectively describing the scene, objects, and activity it contains.
HAVE A SPECIFIC REQUIREMENT?
Tell us what your model needs. We’ll help you scope the annotation capabilities that fit your project.
Backed by deep domain expertise across 20+ industry verticals, we collect and annotate data your models can rely on.
We audit, correct and validate auto-annotated aerial data against your guidelines before it reaches your training pipeline.
Whether you need precisely annotated training data, real-world data collection, a dedicated in-house team, or other staffing solutions, Qualitas Global delivers all three under one roof. Backed by over a decade of experience, we back every engagement with a risk-free 2-day pilot before you commit.