LLM Response Evaluation
We evaluate AI-generated responses against predefined criteria such as accuracy, relevance, completeness, clarity, coherence, and instruction following. Annotators review the response and determine whether it meets the expected quality standards.
Response Ranking and Preference Annotation
We compare two or more AI-generated responses and identify which response is better based on customer-defined criteria. Annotators may also provide a reason for the preference, helping identify which type of response the model should generate.
Instruction-Following Evaluation
We assess whether the AI model has correctly understood and followed the user's instructions. This includes checking the requested format, specific requirements, restrictions, and whether the response actually addresses the user's request.
Text Classification
We classify text into predefined categories based on the customer's requirements. This can include topic, intent, content type, sentiment, query type, or other project-specific classifications.
Intent and Query Understanding
We identify the underlying intent behind a user's query and assign the appropriate category. The team is trained to distinguish between similar or closely related intents and handle ambiguous queries consistently.
Content Quality Evaluation
We review AI-generated content for quality, relevance, readability, coherence, completeness, and accuracy. The objective is to determine whether the generated content is useful and appropriate for the intended use case.
Human Feedback / RLHF
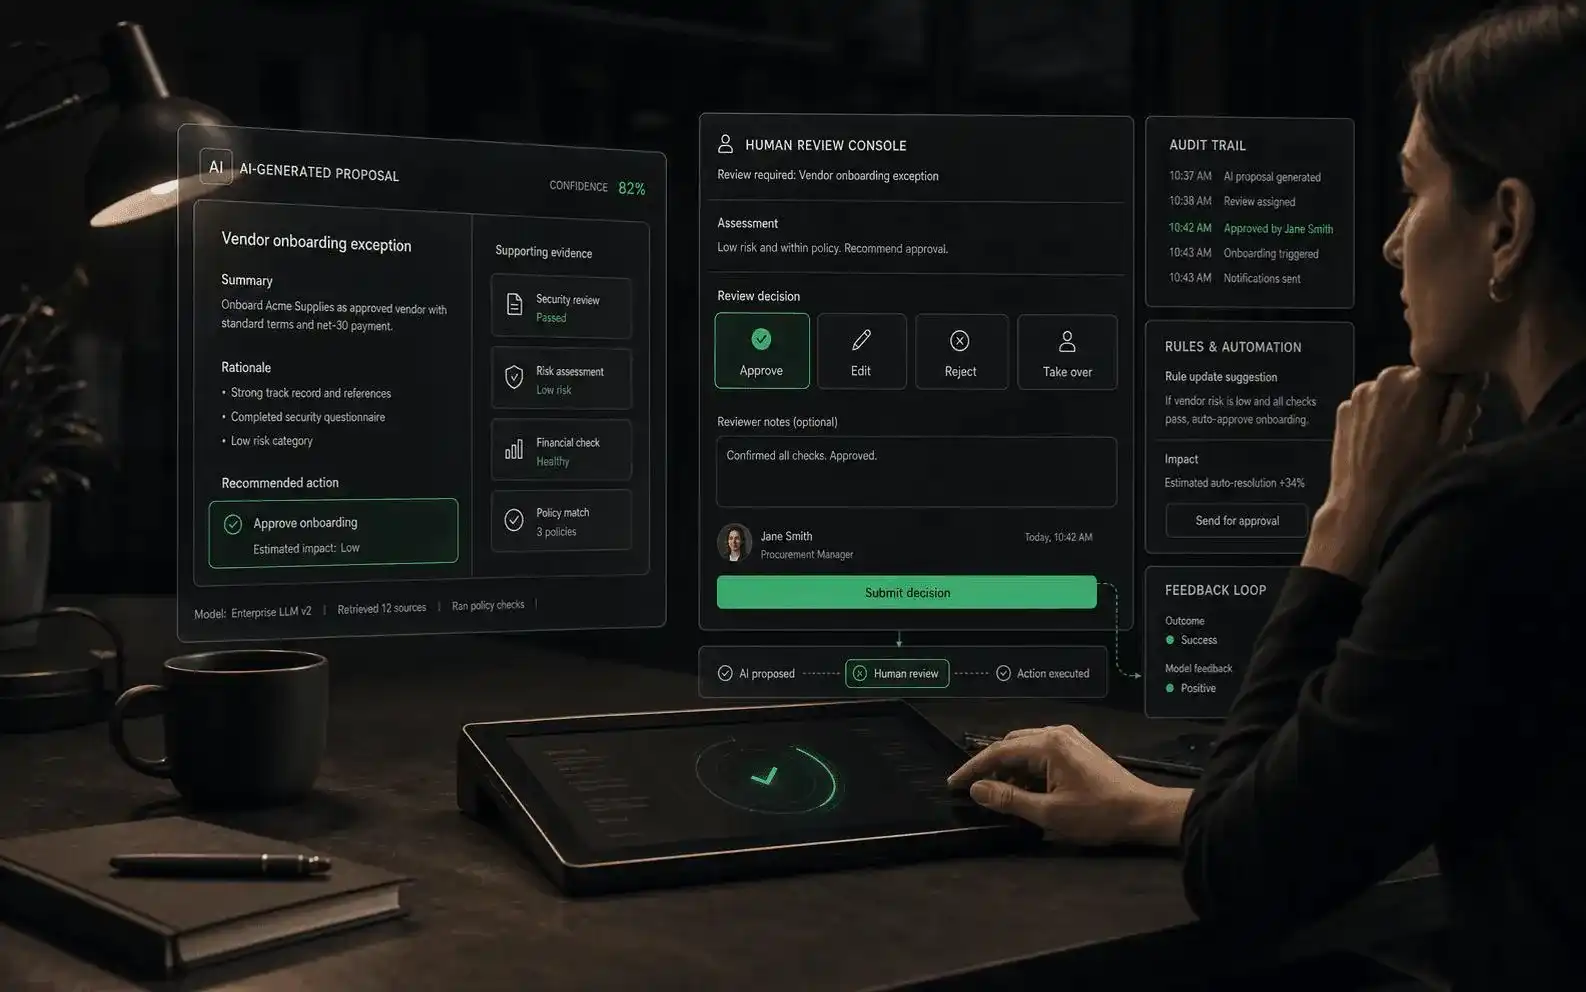
We provide structured human feedback on AI-generated outputs. Annotators can assign scores, rankings, labels, or qualitative feedback based on detailed evaluation guidelines. This feedback can be used to improve the performance and behavior of AI models.
Safety and Policy Evaluation
We review AI-generated content against customer-defined safety and policy guidelines. The team identifies content that may be unsafe, inappropriate, harmful, or non-compliant and applies the appropriate classification.
Prompt and Response Evaluation
We evaluate the relationship between the user's prompt and the model's response. The focus is on whether the model correctly understood the request and generated a response that satisfies the requirements of the prompt.
Factuality and Hallucination Review
We review model responses to identify incorrect, unsupported, or misleading information. Where reference material or expected answers are available, the response is compared against the source information.
Image Description and Captioning
We create structured descriptions of images based on customer-defined requirements. Annotators identify the key elements, objects, actions, relationships, and overall context within an image and convert them into natural-language descriptions.
The descriptions can be generated within a defined character or word limit, ensuring consistency across the dataset. Teams are trained on the required writing style, level of detail, terminology, and formatting before production.
Video Description and Captioning
We create descriptions of video content by reviewing the visual sequence and capturing the key actions, events, objects, interactions, and overall context.
Depending on the requirement, descriptions can be created for the complete video or specific segments, while following a predefined character or word limit. The team is trained to maintain consistency in the level of detail, writing style, timestamps/segments, and terminology specified by the customer.