AUDIO DATA COLLECTION
Monologues, dialogues, and multilingual speech data collected across 20+ languages, delivered ready for ASR, TTS, and voice assistant training.
- 13+Years of Expertise, Since 2014
- 20+Industries Served
- 97%Quality Benchmark
- 24x7x365Secure Operations
- Ready-to-License Datasets
- Custom Purpose-Built Data Collection
- Multi-Industry Coverage
- Real-World Environments
Data Quality & Accuracy
Precise, model-ready data
Privacy & Compliance
Secure, compliant data handling
Ethical Sourcing
Ethical, fully consented, and diverse
Scalability & Flexibility
Scalable, adaptable data operations
Domain Expertise
Specialized industry expertise
- Consented Data
- GDPR & HIPAA Compliant
- TISAX Level 3
- ISO 27001 & 9001 Certified
INTRODUCTION
Speech Data That Reflects Real Voices
Speech recognition and voice AI models fail most often not because of weak architecture, but because of narrow training data that does not reflect real accents, speech patterns, background noise, or conversational structure.
Qualitas Global has collected more than 43,000 hours of speech data across 20+ languages, spanning Asian, African, European, and Slavic regions, including Germany, Greece, Romania, Serbia, and Ukraine.
Each audio collection project is scoped around the specific speech scenario your model needs, whether that is single-speaker monologues, multi-party group conversations, or acoustic conditions for far-field recognition. Data is captured with consented participants, structured metadata, and quality validation at every stage, so your model trains on speech that matches its real deployment environment.
OUR CAPABILITIES
Audio Data Collection Across Speech Scenarios
Monologues
Single-speaker audio across scripted and unscripted speech, used to train models on individual speech patterns, pacing, and pronunciation without the complexity of speaker overlap. This dataset type forms a baseline for voice recognition systems before layering in more complex conversational data.
Dialogues
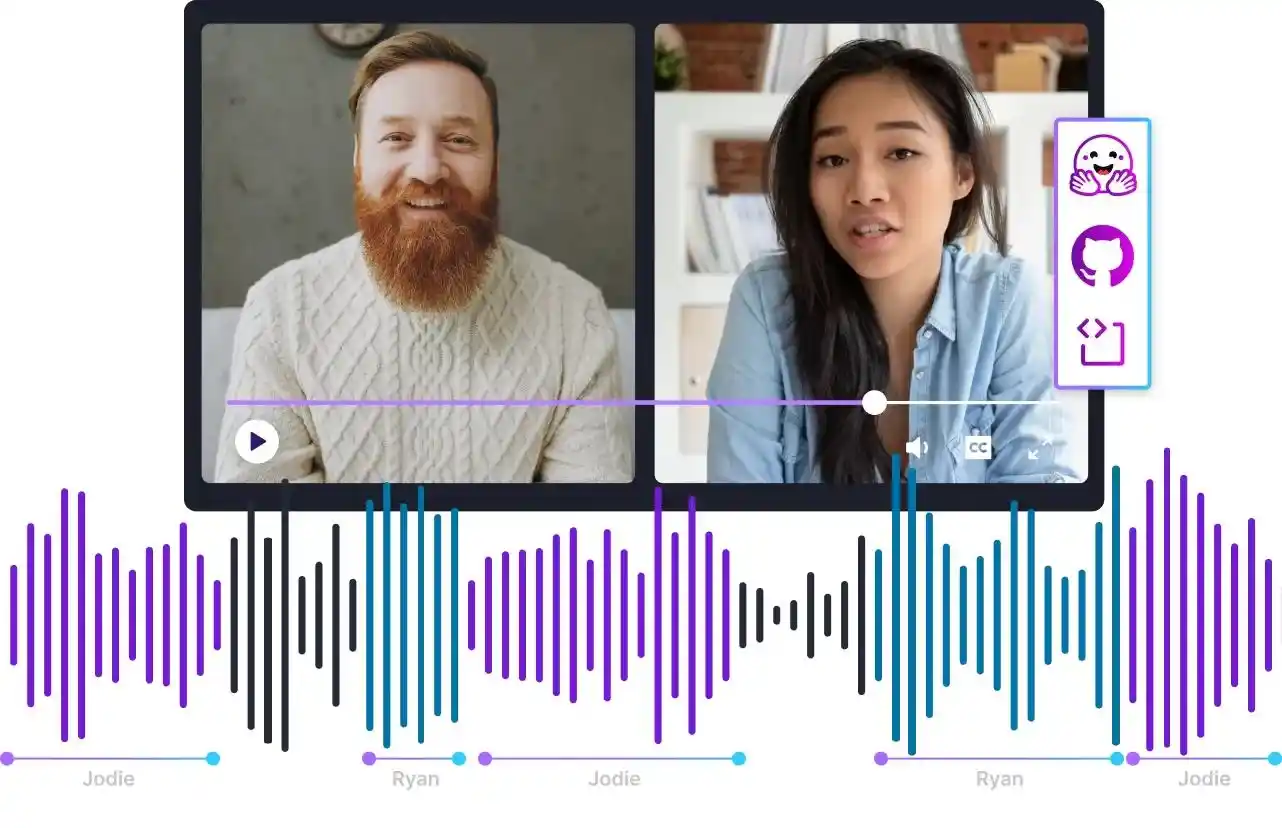
Two-speaker conversations across scripted and natural exchanges, training models to recognize turn-taking, interruption, and speaker-to-speaker context. This is a core dataset type for voice assistants and conversational AI that must track more than one speaker at a time.
Group Conversations
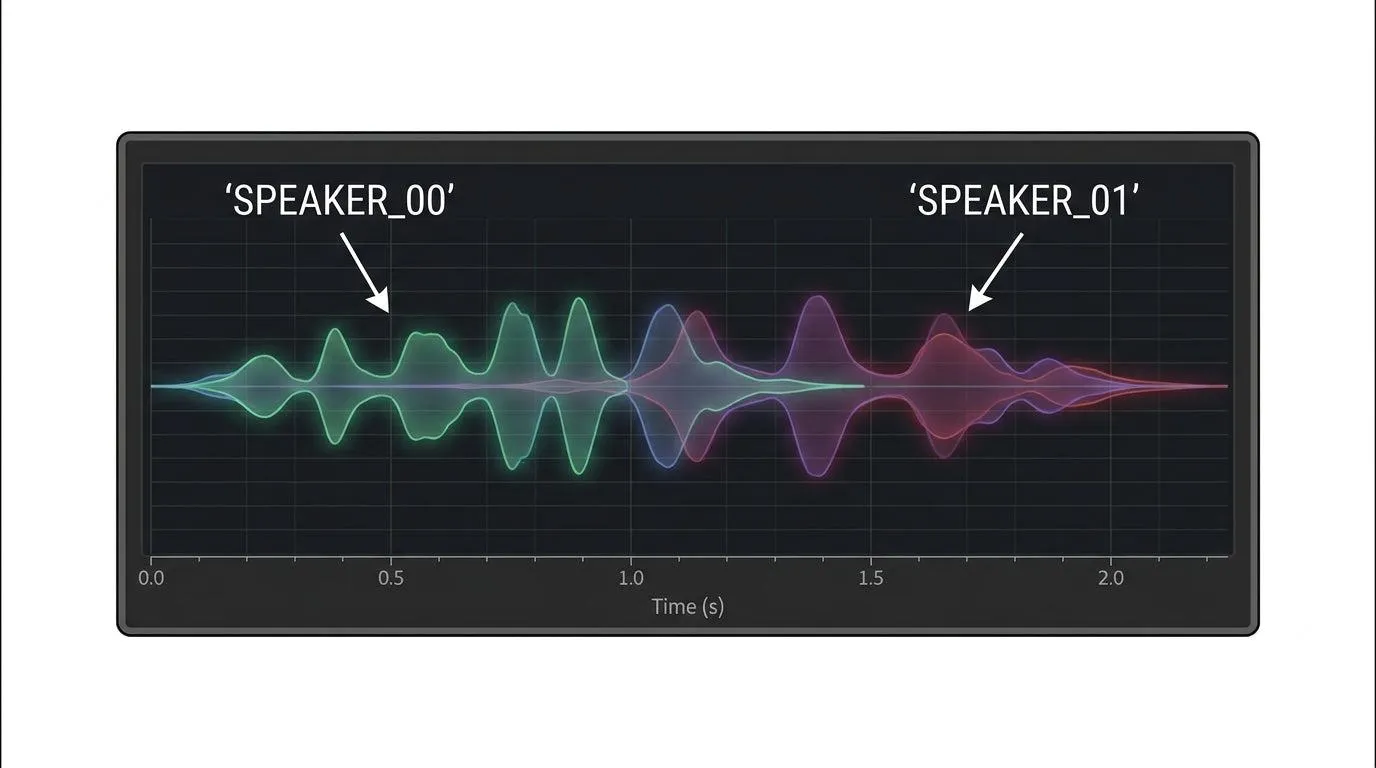
Multi-speaker audio in natural settings, training models to separate and identify individual speakers within overlapping speech, background noise, and shifting conversational focus. Supports speaker diarization and meeting transcription applications where accuracy depends on distinguishing multiple voices in real time.
Call Center Recordings
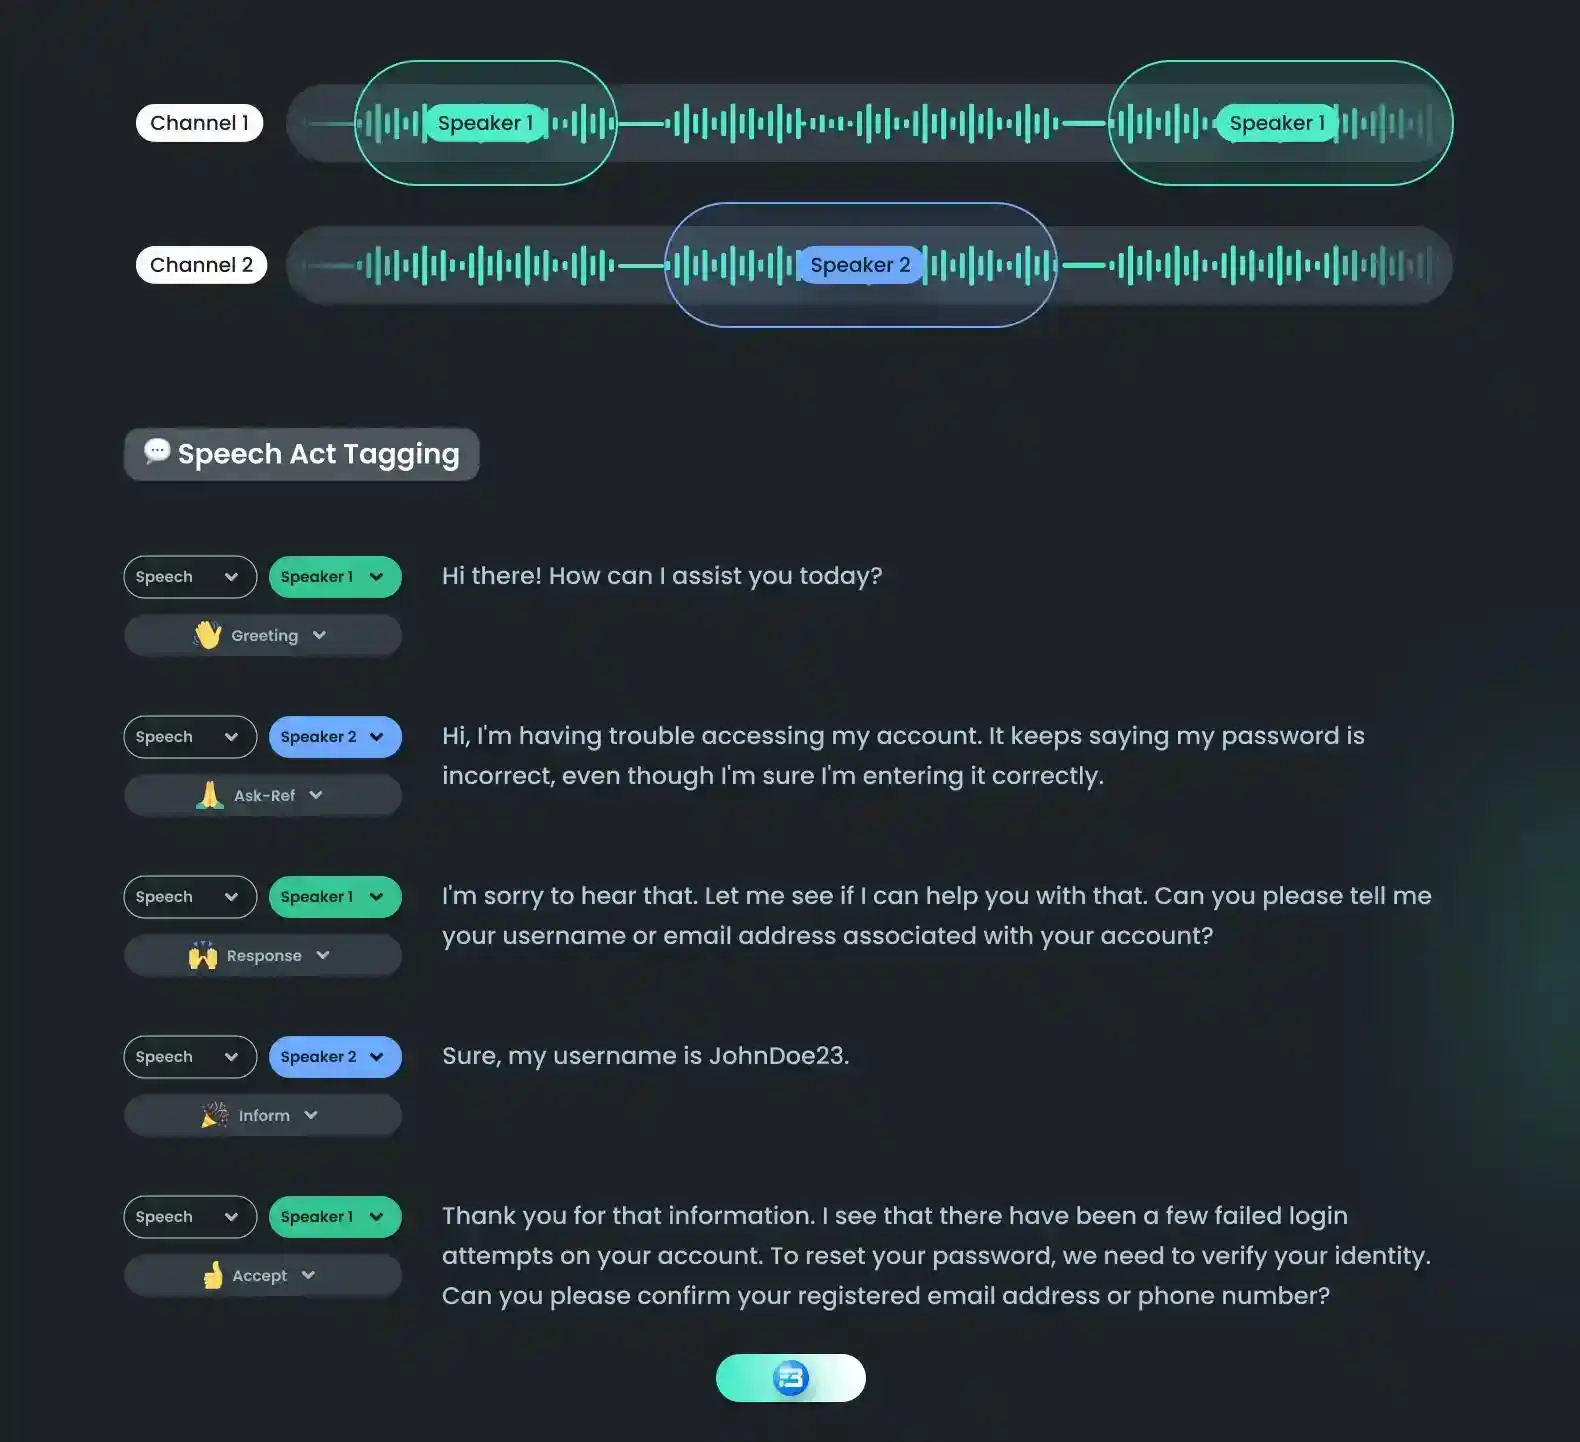
Real or simulated customer service interactions, including hold patterns, escalation language, and resolution dialogue, structured for training speech models used in support automation and quality monitoring. Reflects authentic customer intent and emotional tone that scripted datasets cannot replicate.
Acoustic Data Collection
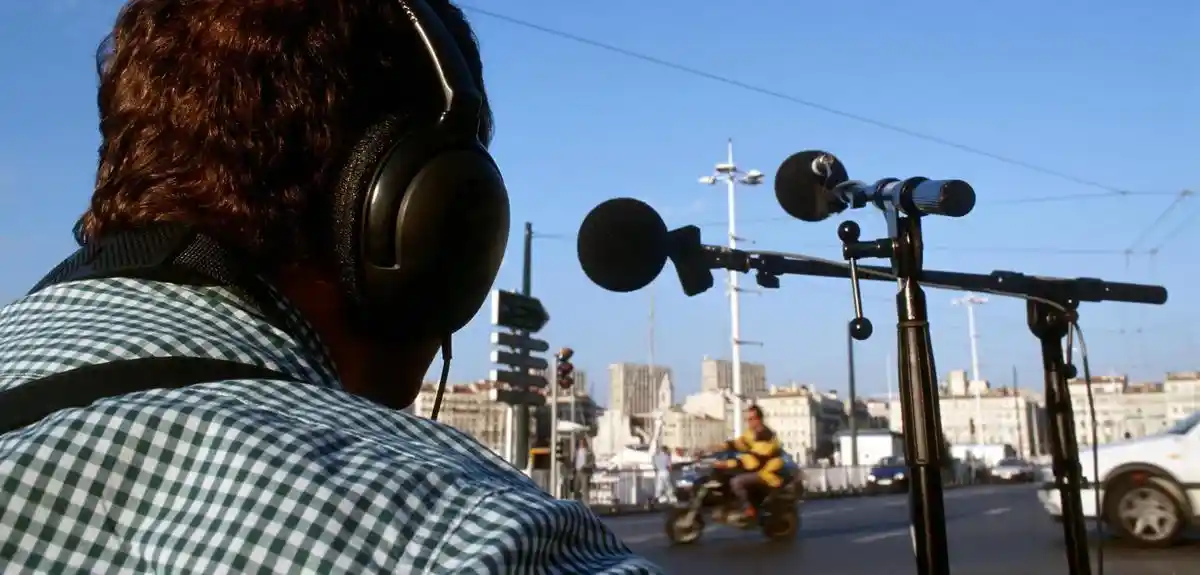
Audio captured across varied environmental conditions, including background noise, reverberation, and device-specific microphone characteristics, used to train models for robustness in real-world listening conditions rather than clean studio audio alone. Essential for voice models deployed in vehicles, public spaces, or industrial environments.
Natural Language Utterance Collection
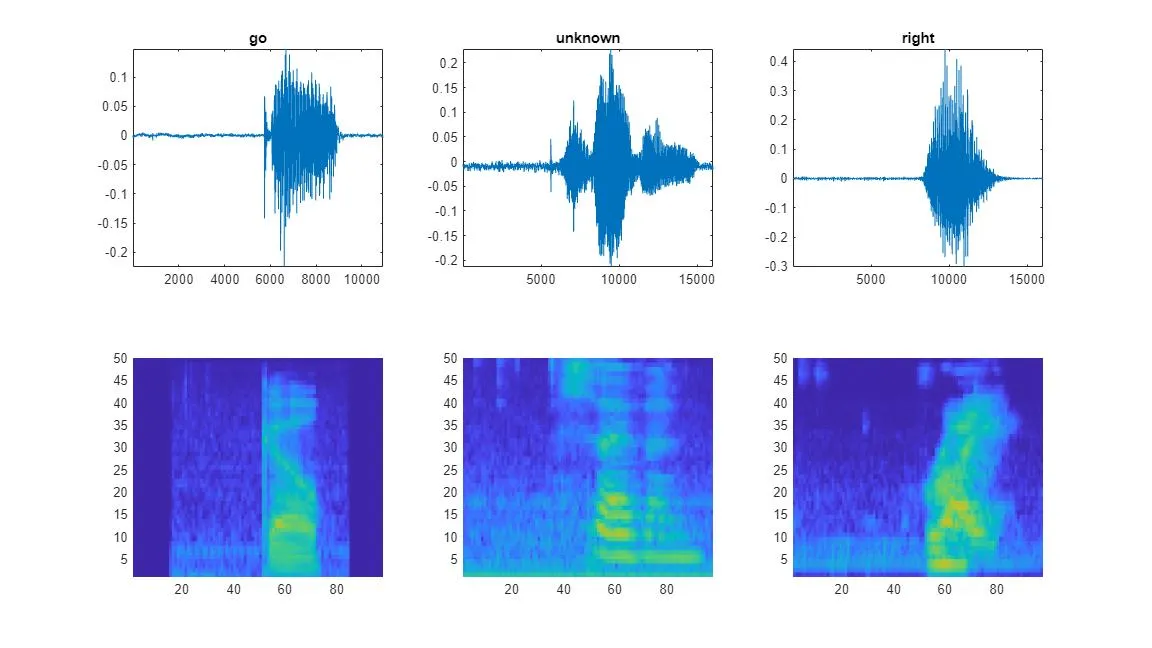
Short, natural spoken utterances collected for training intent recognition and command-based voice systems, capturing the way people actually phrase requests rather than idealized scripted commands. Foundational for voice command accuracy in smart devices and voice-controlled applications.
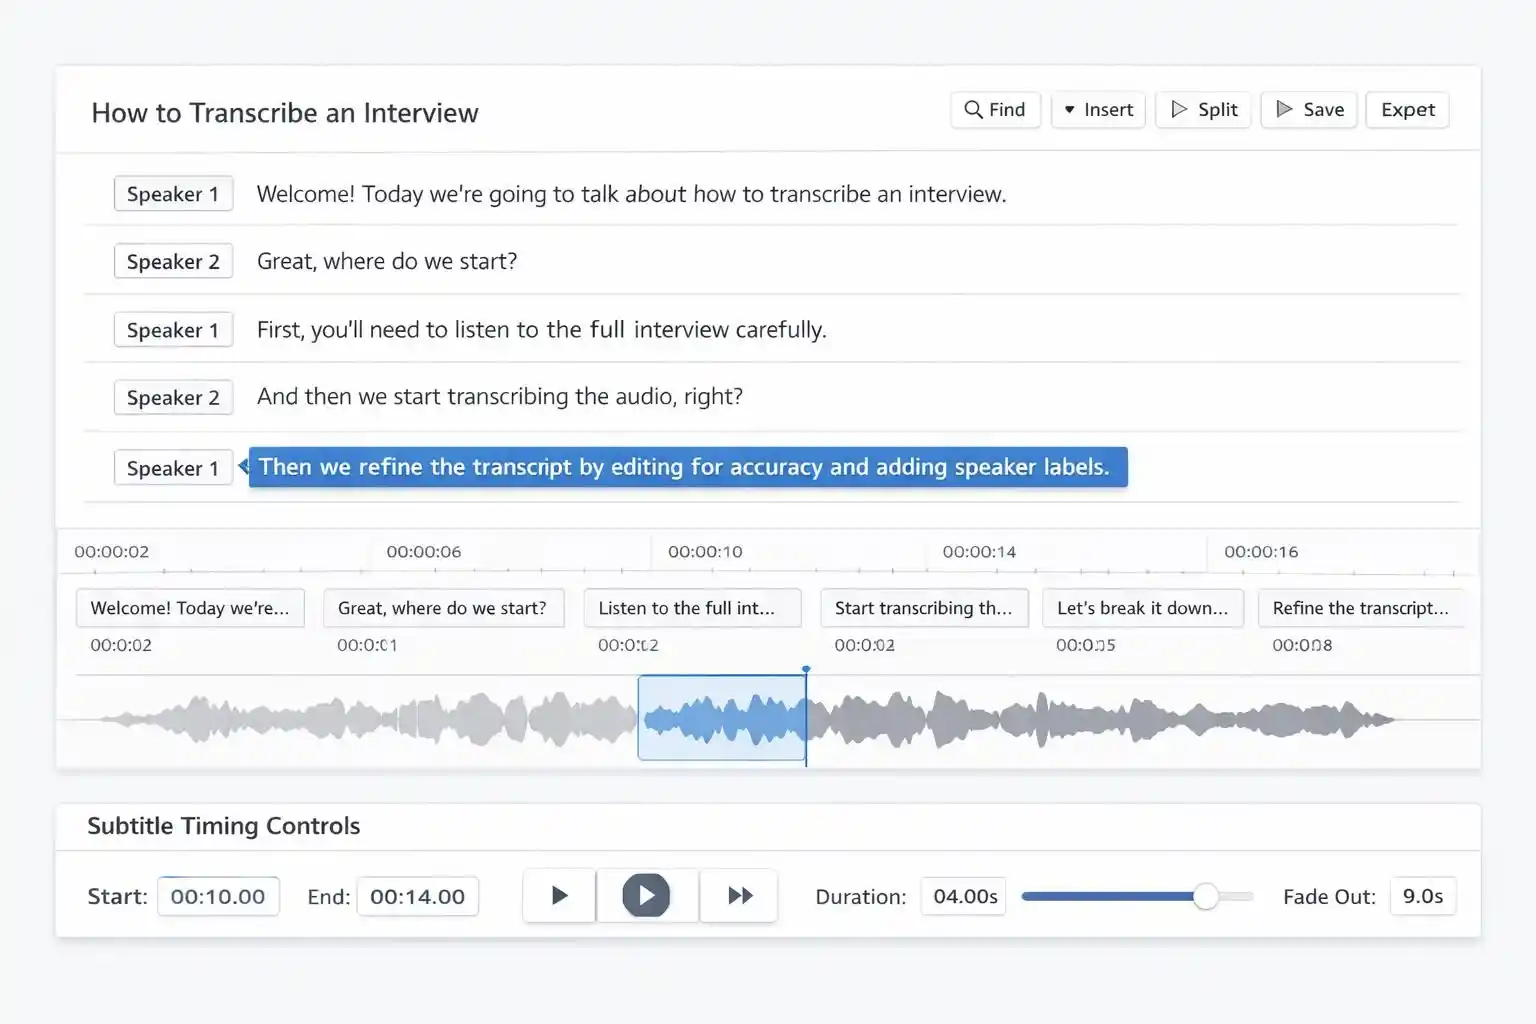
Automatic Speech Recognition (ASR)
Data collection structured specifically for training and benchmarking speech-to-text models, pairing audio with accurate transcriptions across accents, dialects, and speaking speeds. Each dataset is validated for transcription accuracy before delivery, since ASR model performance depends directly on transcript precision.
Digital / Virtual Assistants
Speech data collected specifically for training and fine-tuning digital and virtual assistant models, including wake-word detection, command recognition, and follow-up query handling across languages. Structured to reflect real household and workplace usage patterns rather than lab-controlled speech alone.
Multilingual Speech/Audio Training Data
43,000+Hours of speech data across 20+ languages
Speech data spanning 20+ languages across Asian, African, European, and Slavic regions, giving language models exposure to accent variation, code-switching, and region-specific pronunciation. Critical for any voice model intended for global rather than single-market deployment.
Text-to-Speech (TTS)
High-quality voice recordings paired with precise text scripts, capturing the natural intonation, pacing, and emotional range needed to train synthetic voice models. Each recording is collected under controlled conditions to meet the audio clarity standards TTS model training requires.
Deep Domain Expertise Across
20+ Industry Verticals
Backed by deep domain expertise across 20+ industry verticals, we collect and annotate data your models can rely on.
Data, Collected &Annotated.Teams, Deployed.Ready When You Are.
Whether you need precisely annotated training data, real-world data collection, a dedicated in-house team, or other staffing solutions, Qualitas Global delivers all three under one roof. Backed by over a decade of experience, we back every engagement with a risk-free 2-day pilot before you commit.