TEXT DATA COLLECTION
Sourced, licensed, and structured text data across multiple content categories and multiple languages, delivered ready for NLP, LLM, and search model training.
- 13+Years of Expertise, Since 2014
- 20+Industries Served
- 97%Quality Benchmark
- 24x7x365Secure Operations
- Ready-to-License Datasets
- Custom Purpose-Built Data Collection
- Multi-Industry Coverage
- Real-World Environments
Data Quality & Accuracy
Precise, model-ready data
Privacy & Compliance
Secure, compliant data handling
Ethical Sourcing
Ethical, fully consented, and diverse
Scalability & Flexibility
Scalable, adaptable data operations
Domain Expertise
Specialized industry expertise
- Consented Data
- GDPR & HIPAA Compliant
- TISAX Level 3
- ISO 27001 & 9001 Certified
INTRODUCTION
Text Data Collection for Real-World AI
Language models (LLMs) are only as accurate as the text they are trained on.
An AI model trained on narrow, poorly sourced, or improperly licensed text data will misread context, miss domain-specific terminology, and fail when it meets real user queries. Qualitas Global collects text data across digital publications, forums, technical documents, legal records, and more, sourced and rights-cleared for commercial AI training use.
Every dataset is collected under a defined protocol covering source diversity, licensing compliance, and metadata capture, then validated against your project specification before delivery. This means your model receives text data that reflects how people actually write, argue, request support, and communicate across formats, not a narrow slice scraped without structure or consent tracking.
OUR CAPABILITIES
Text Data Collection Across Diverse Sources
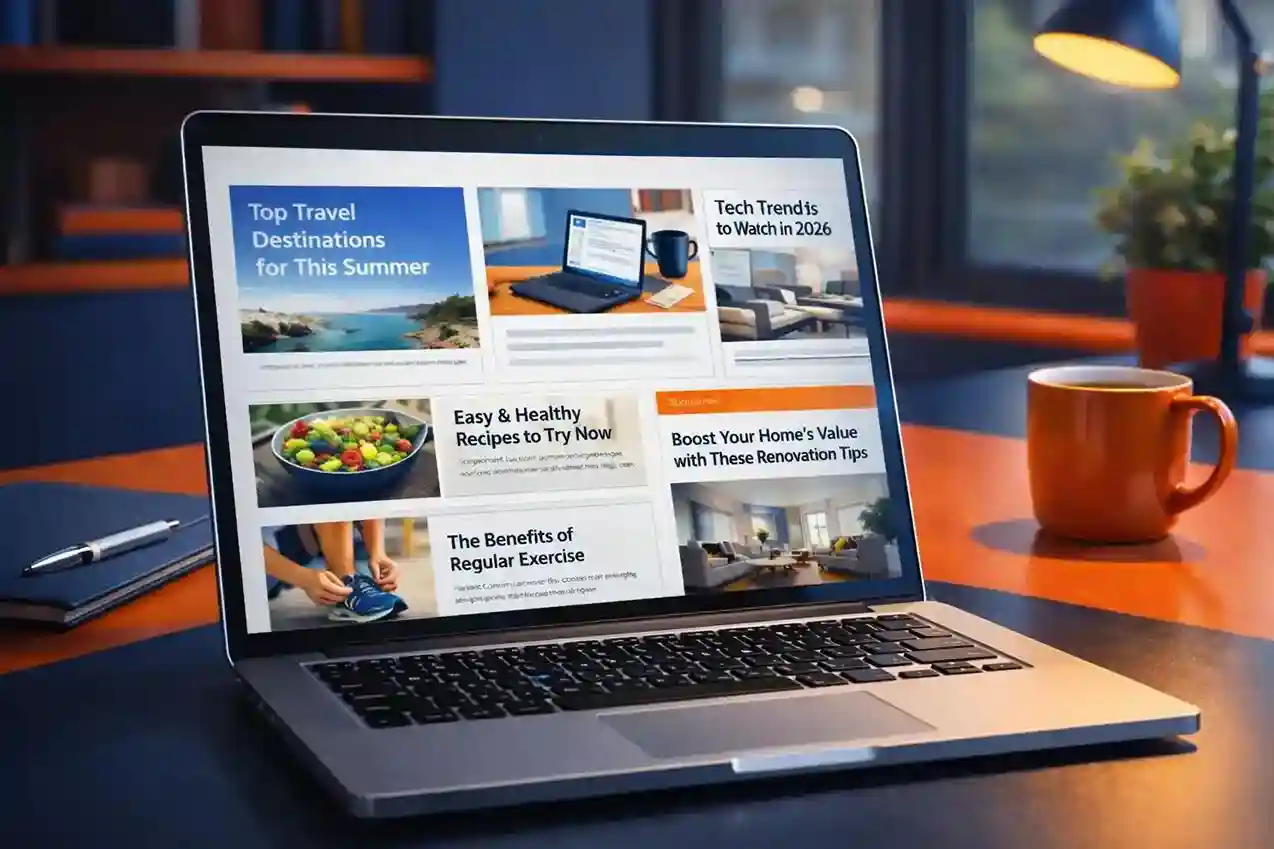
Digital Publications
Qualitas Global collects text data from digital publications including news articles, magazines, blogs, and online editorial content, capturing writing style, tone, and topic coverage across genres. This data supports language models that need to summarize, classify, or generate publication-style content with accuracy.
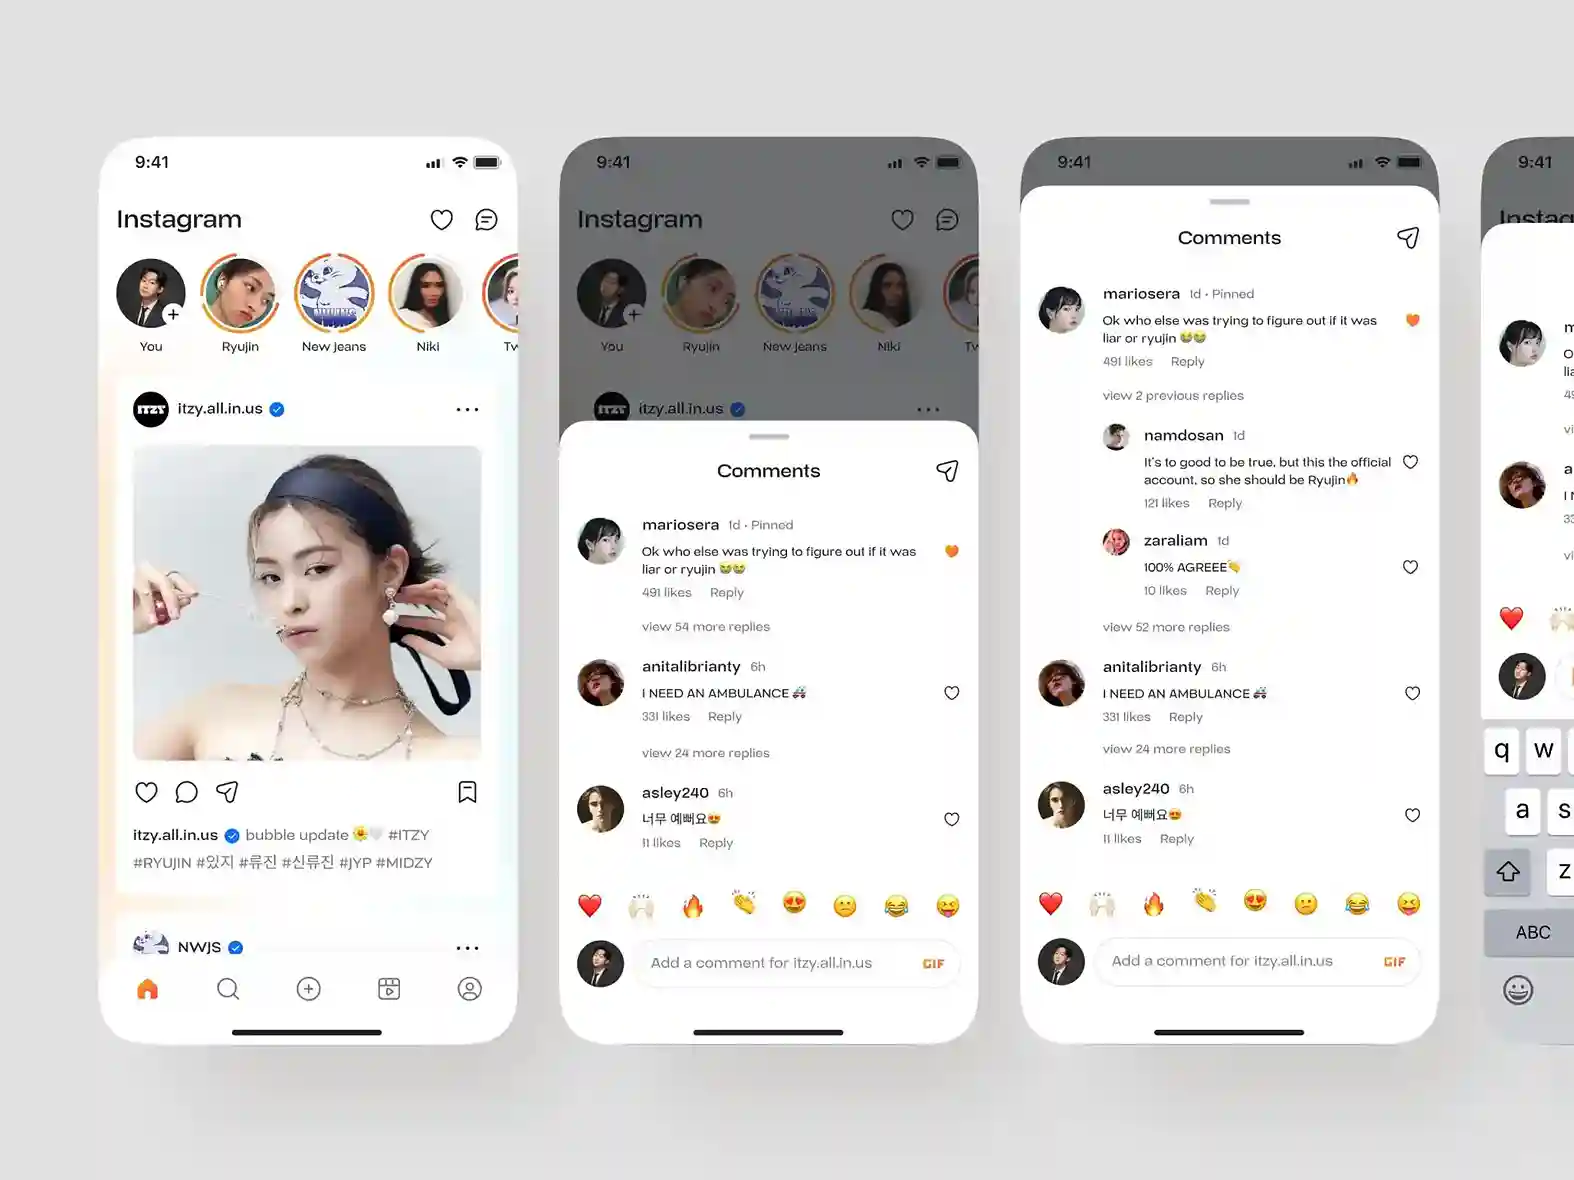
Social Media
Social media text data collection covers posts, comments, captions, and threaded replies across major platforms, capturing informal language patterns, slang, sentiment, and real-time conversational structure. This dataset type is used to train models for sentiment analysis, content moderation, and conversational AI that needs to understand casual, unstructured text.
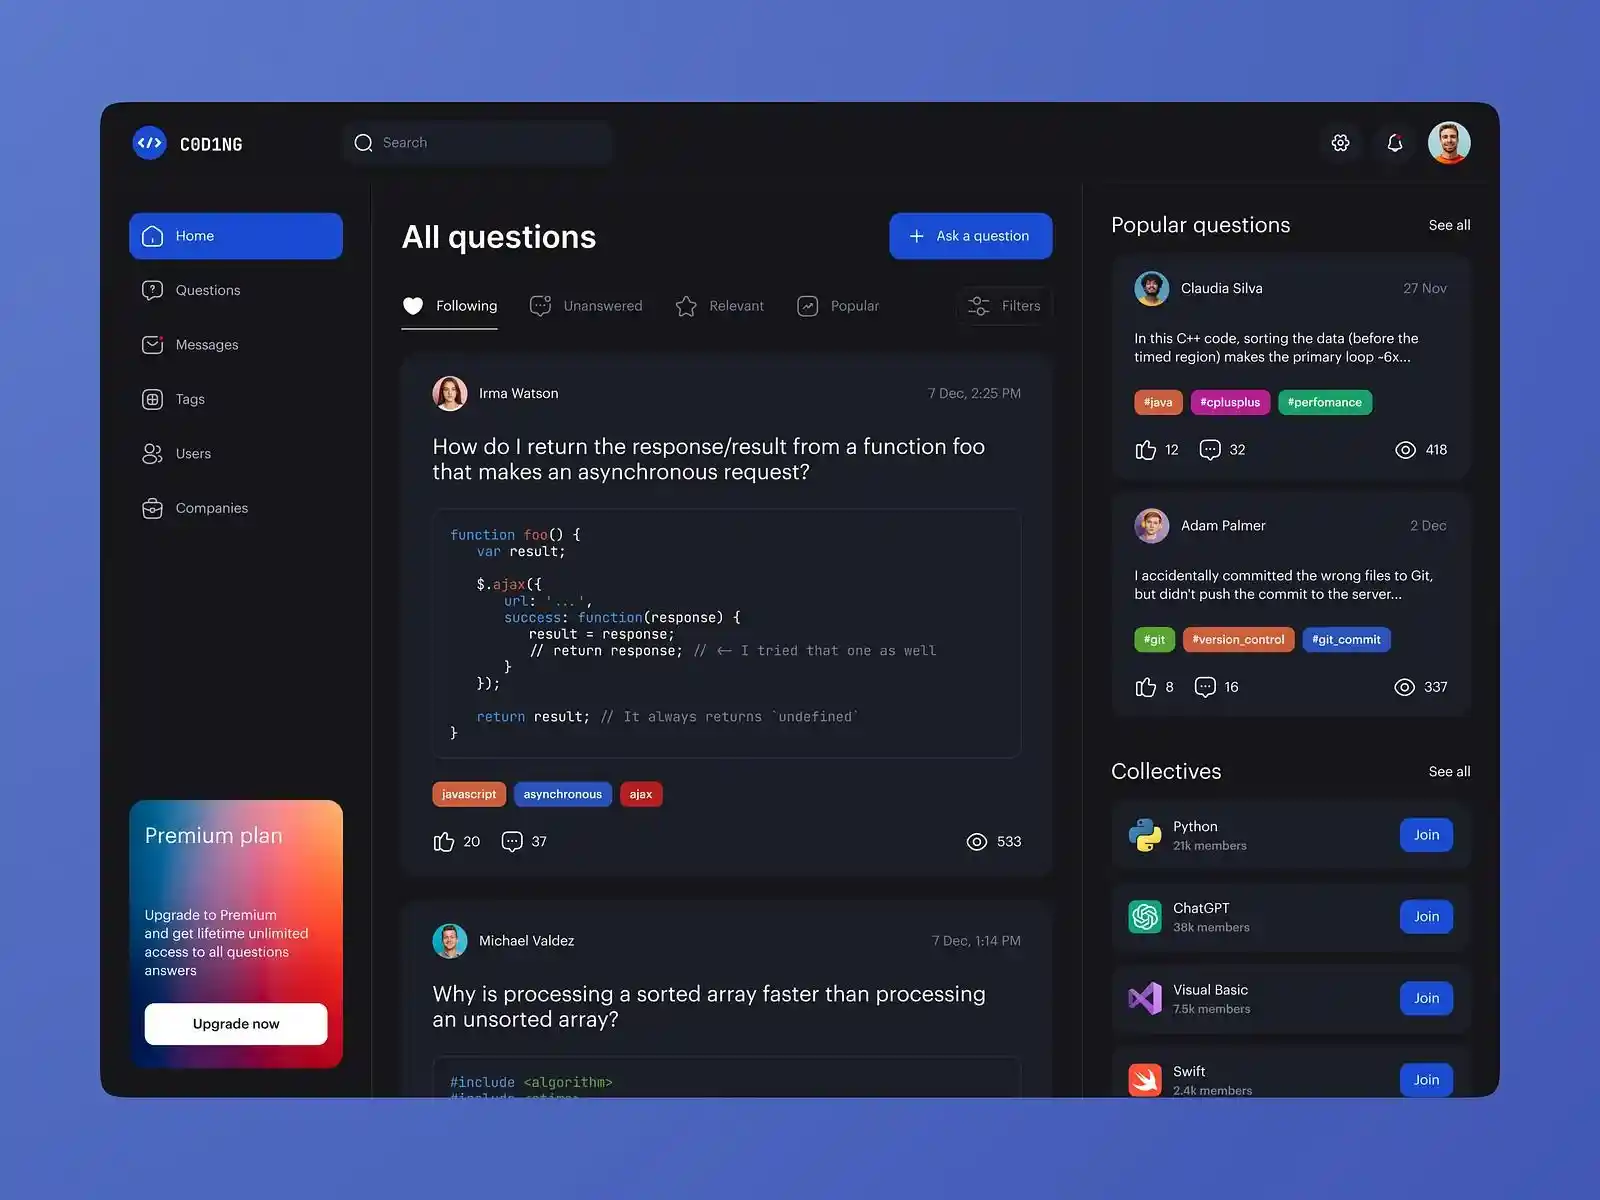
Forums & Community Discussions
Forum and community discussion data captures multi-turn threads, question-and-answer exchanges, and topic-specific community language from platforms where users debate, troubleshoot, and share expertise. This data type is valuable for training models on domain-specific vocabulary and threaded conversational context that single-turn datasets cannot provide.
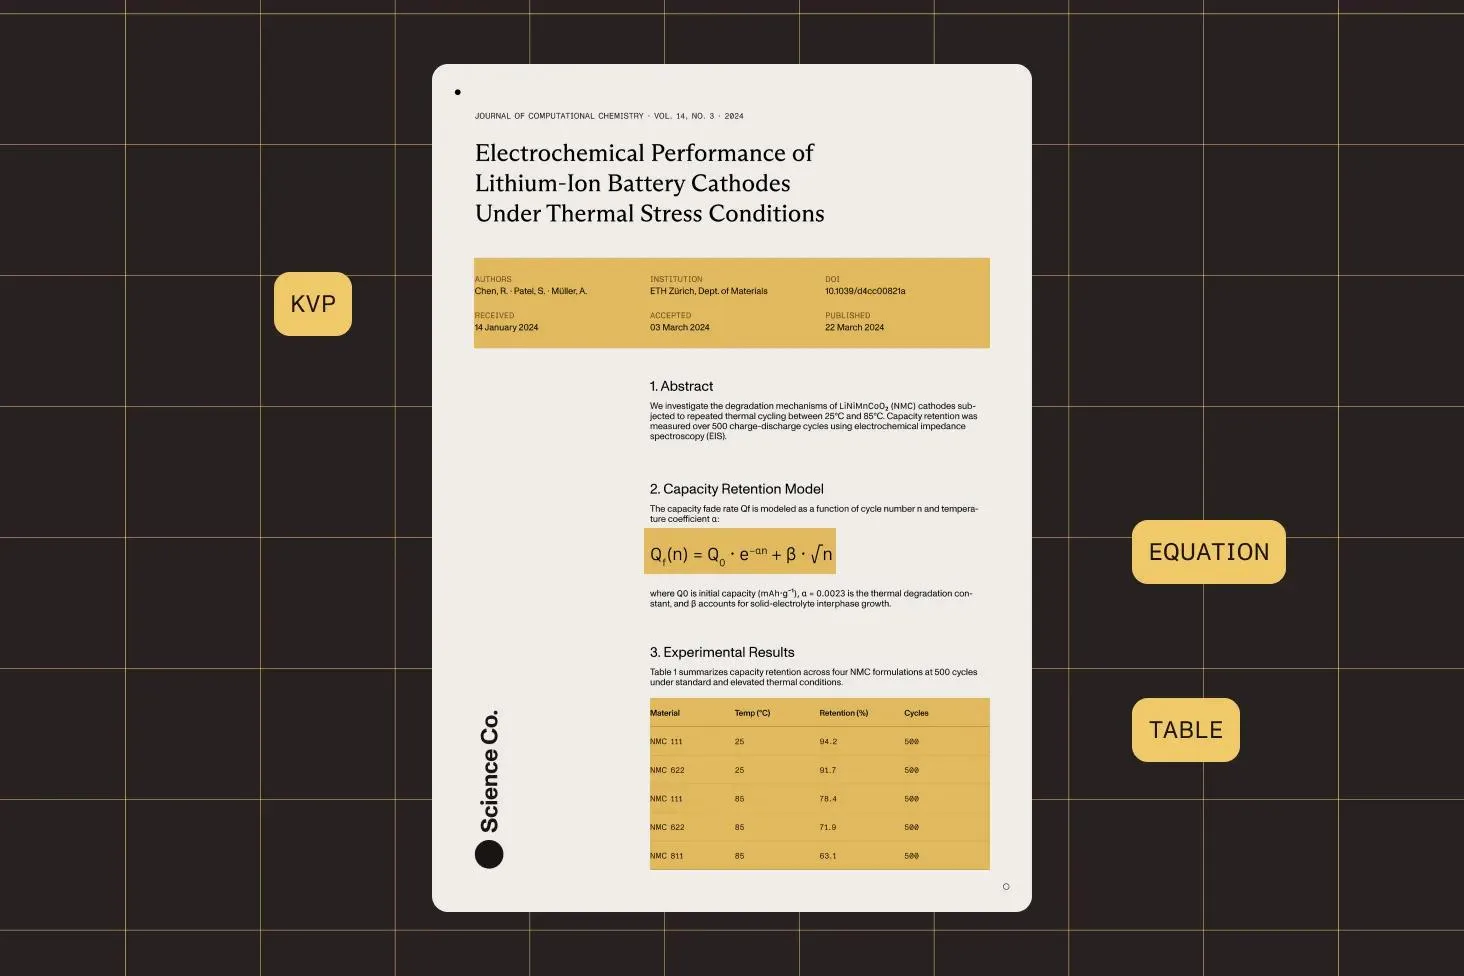
Technical & Academic Texts
This category includes the material in research papers, technical manuals, whitepapers, and academic publications collected across disciplines. It gives language models exposure to formal structure, citation patterns, and specialized terminology needed for research assistance, technical documentation generation, and academic summarization tasks.
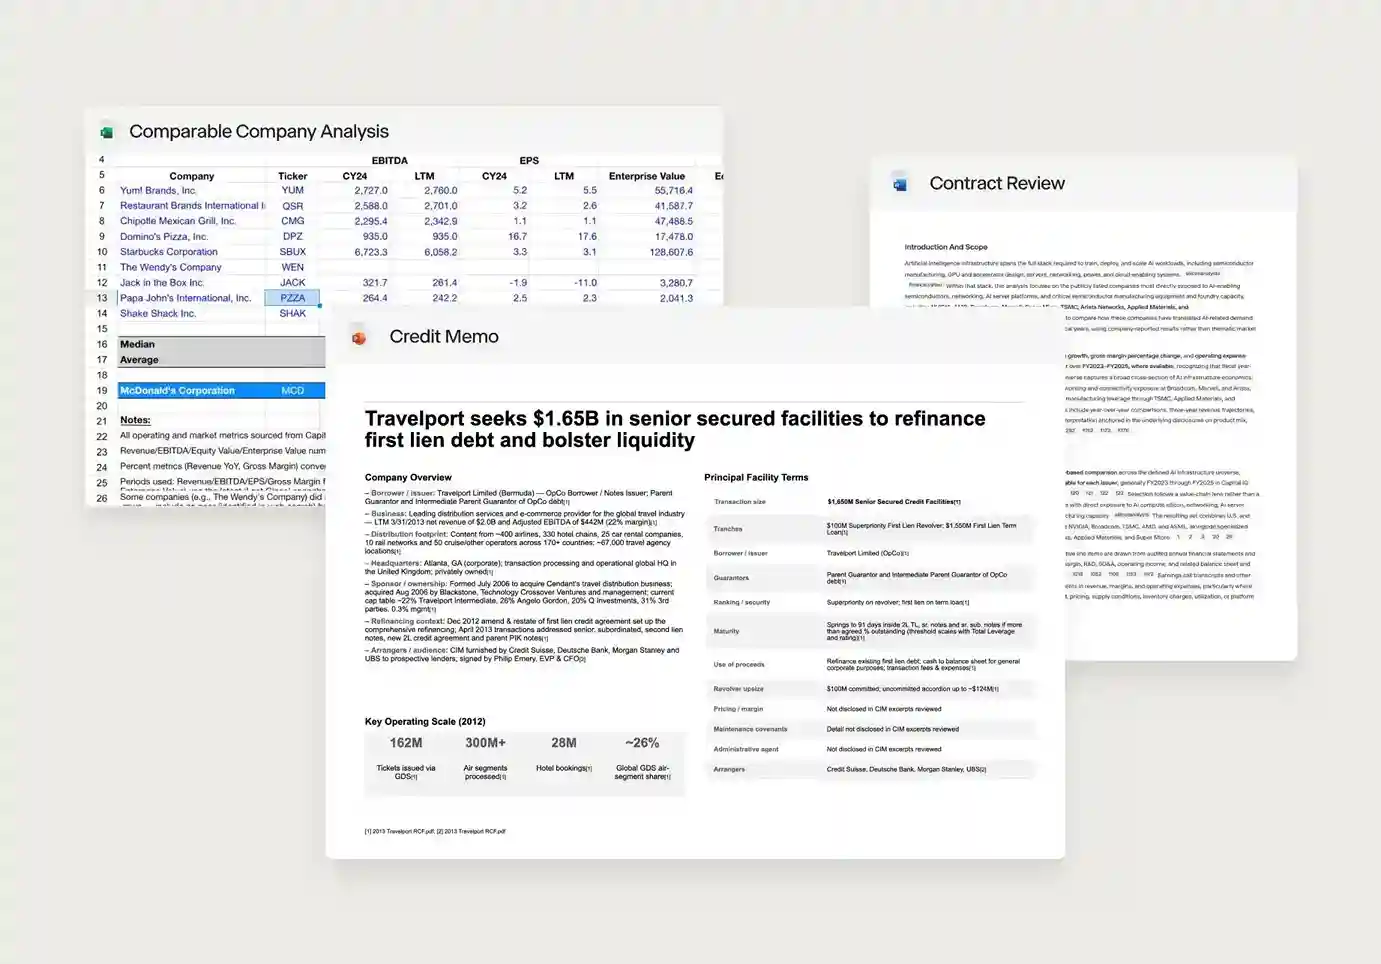
Business & Financial Text
Business and financial text collection covers the content in reports, memos, contracts, financial statements, and internal communications structured for AI training in enterprise and finance-specific language models. Each dataset is collected with attention to formatting conventions and industry terminology that differ from general text.
Legal Texts
Legal text collection includes case law, statutes, contracts, and regulatory filings, capturing the precise, structured language that legal AI applications require. This data supports models built for contract review, legal research assistance, and compliance monitoring, where imprecise language handling carries real business risk.
Literary Works
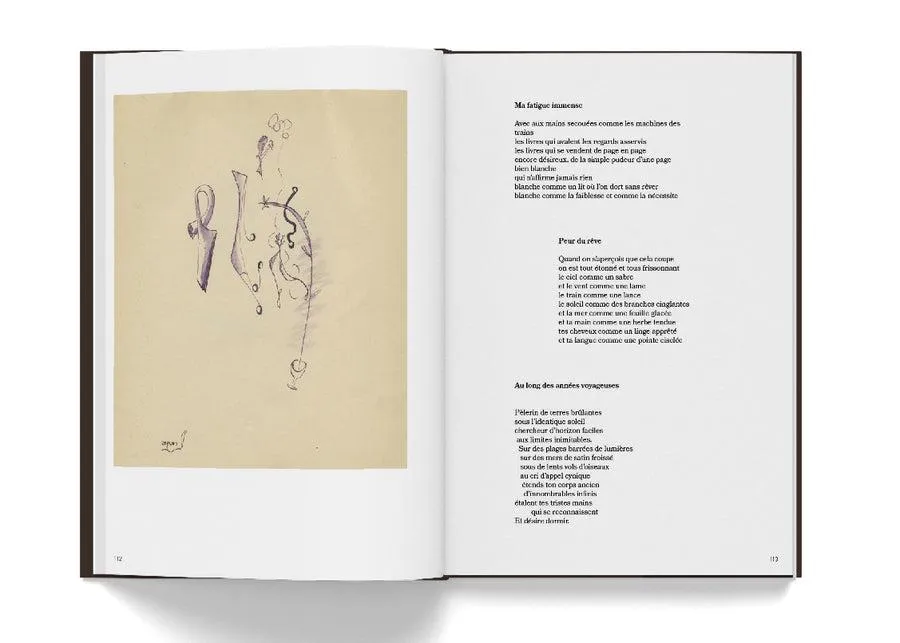
Literary text collection covers text data from fiction, poetry, and long-form creative writing, capturing narrative structure, stylistic variation, and figurative language. This dataset type supports models built for creative writing assistance, style transfer, and literary analysis.
Educational Materials
The educational material collection includes text data from textbooks, course content, lesson plans, and instructional text across subjects and grade levels. This data trains models built for tutoring applications, curriculum generation, and educational content assessment.
Government & Public Records
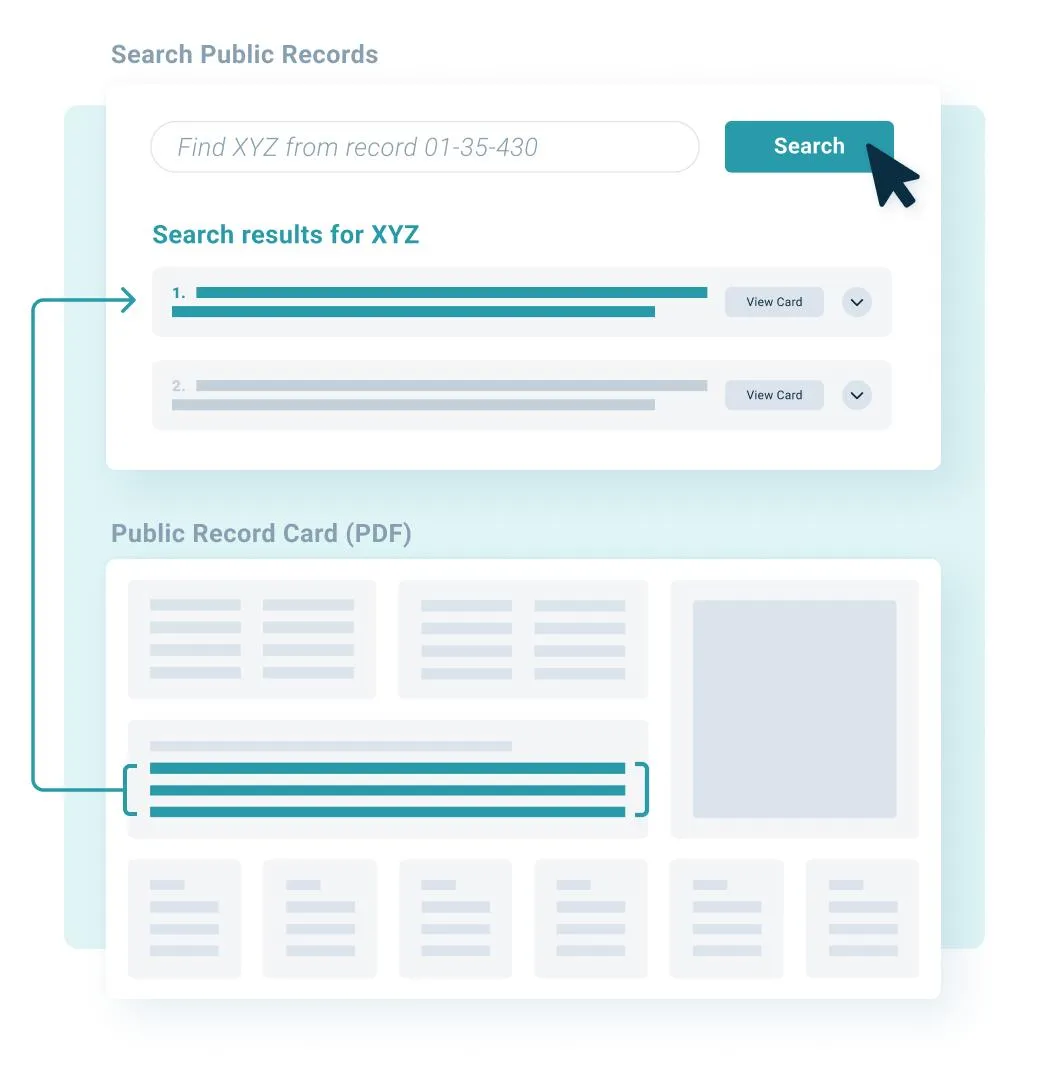
Government and public record collection covers public filings, policy documents, official notices, and administrative records, gathered in line with public data access rules. This supports models used in civic technology, public sector research, and policy analysis applications.
Medical & Healthcare Records
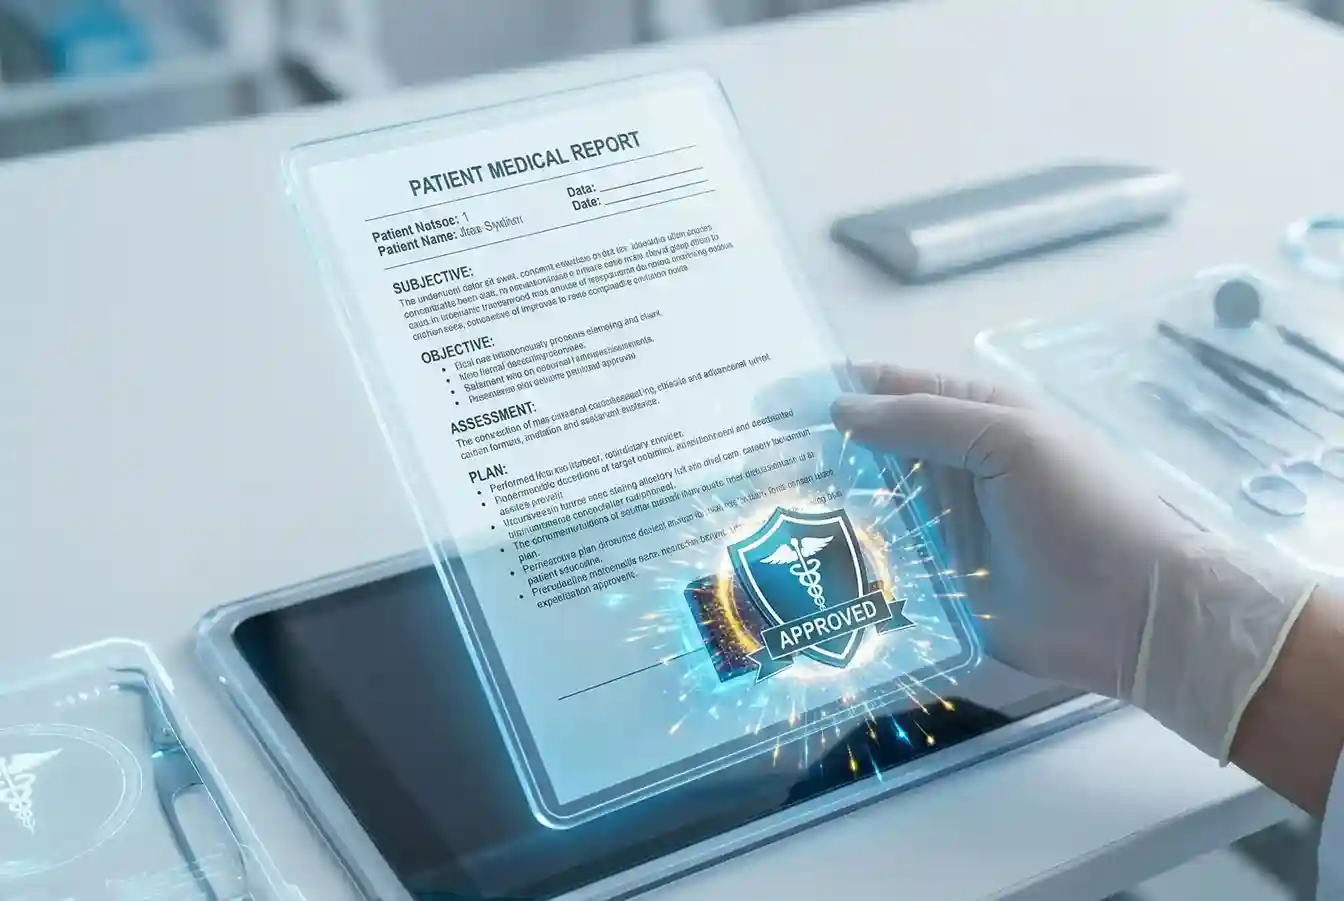
Medical and healthcare text collection covers clinical notes, medical literature, and healthcare documentation, gathered and handled under strict privacy and compliance protocols, including HIPAA and GDPR requirements. These text datasets support clinical NLP models, medical coding automation, and healthcare chatbots that require accurate medical terminology.
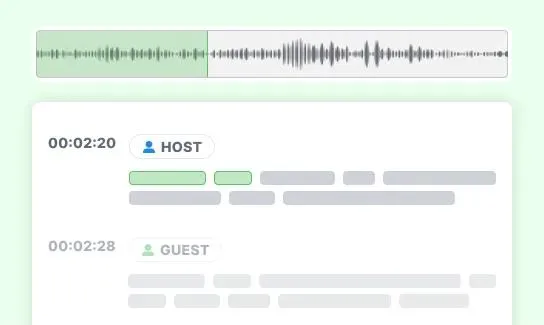
Transcripts
Transcript collection includes text data converted from speech-to-text data from interviews, meetings, podcasts, and recorded conversations, structured with speaker labels and timestamps where required. These text datasets support AI models that need aligned audio-to-text training pairs for transcription accuracy and speaker-aware language understanding.
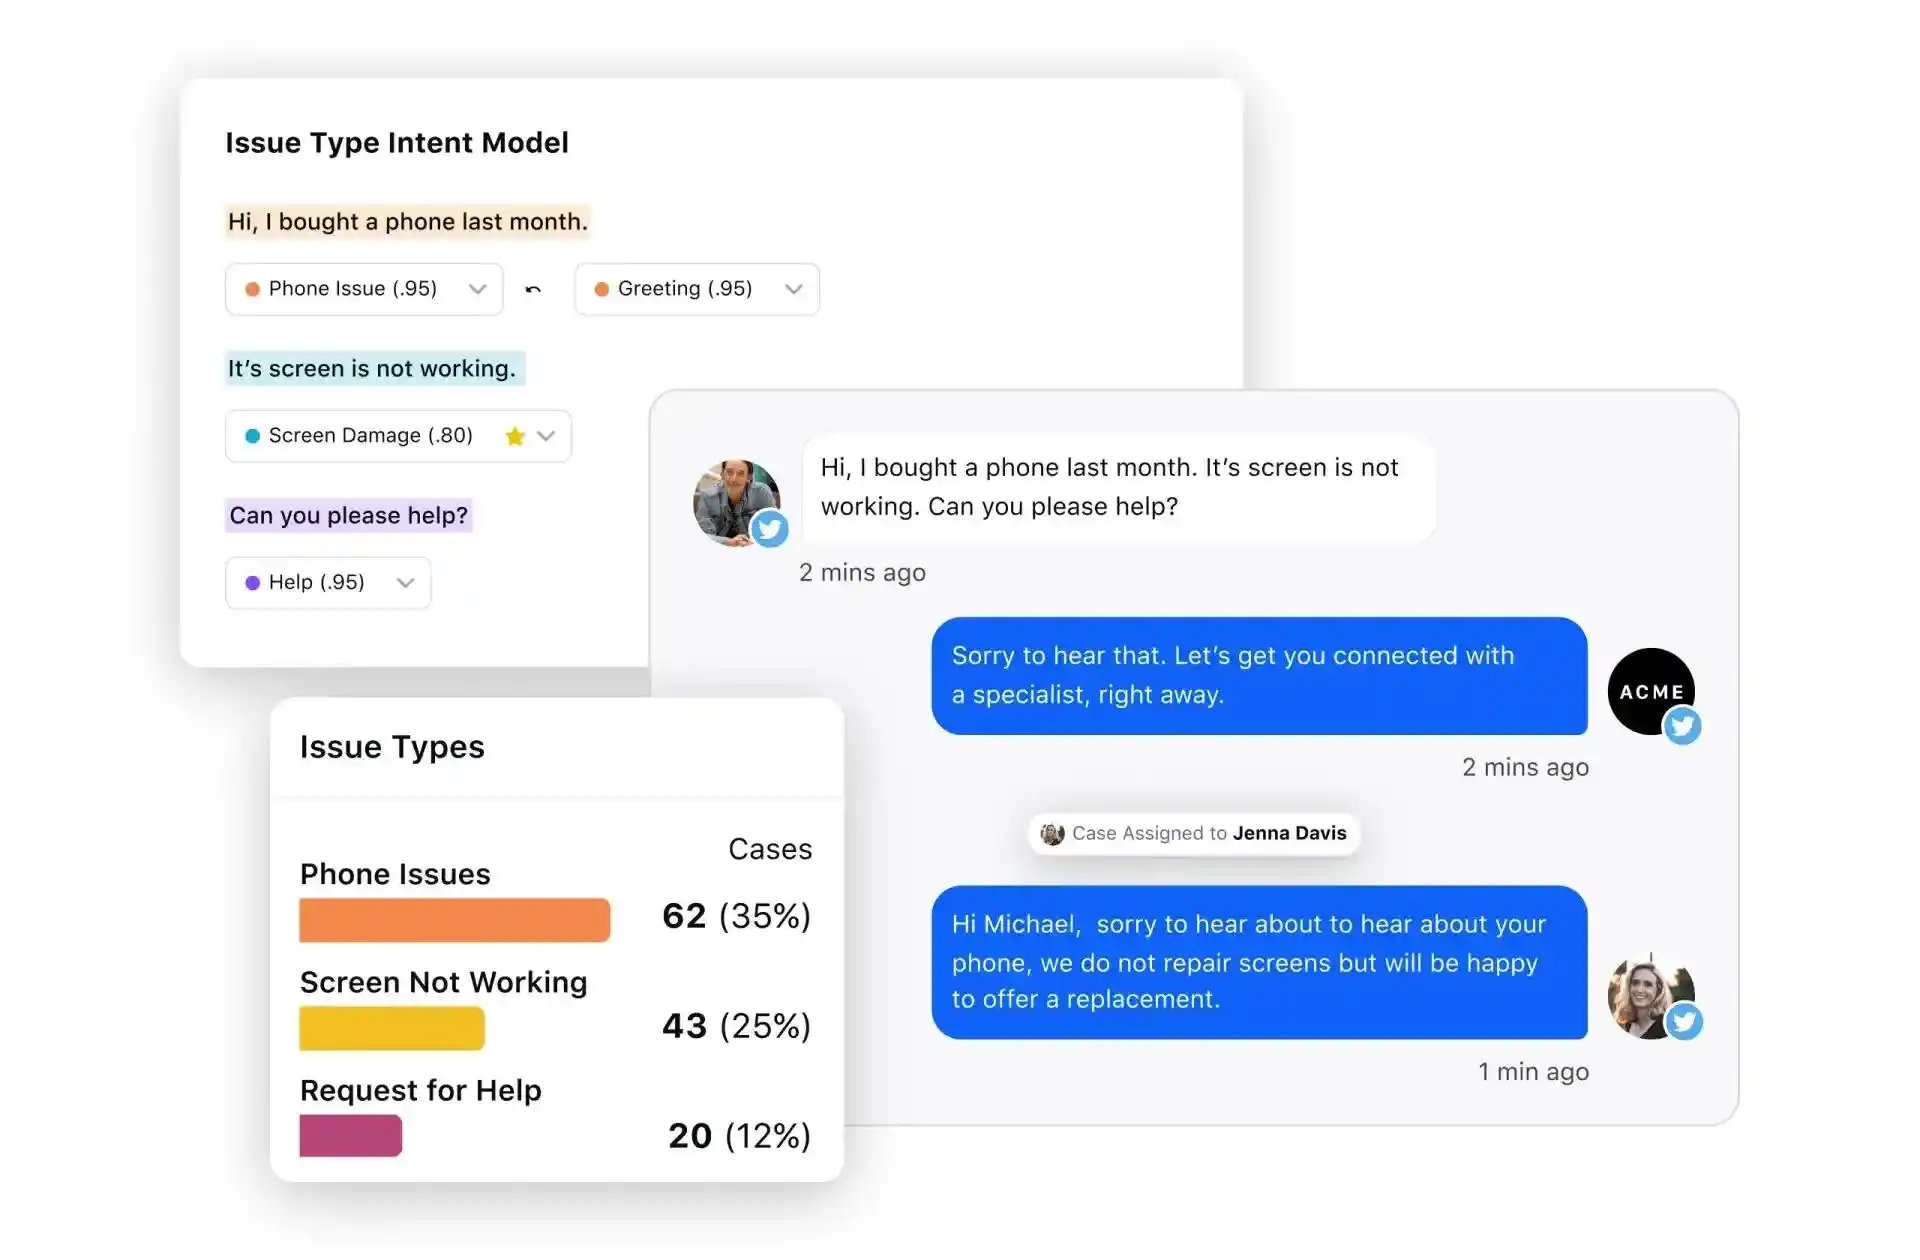
Chatbots & Customer Support Logs
This covers text data from customer support transcripts, chatbot conversation logs, and help desk interactions, capturing real user intent, question phrasing, and resolution language. These text datasets are used to train and fine-tune conversational AI and customer service automation models on authentic support scenarios rather than scripted examples.
Deep Domain Expertise Across
20+ Industry Verticals
Backed by deep domain expertise across 20+ industry verticals, we collect and annotate data your models can rely on.
Data, Collected &Annotated.Teams, Deployed.Ready When You Are.
Whether you need precisely annotated training data, real-world data collection, a dedicated in-house team, or other staffing solutions, Qualitas Global delivers all three under one roof. Backed by over a decade of experience, we back every engagement with a risk-free 2-day pilot before you commit.